SigNoz dashboards
Import the RunsOn Operations, Runners, and Troubleshooting dashboards into SigNoz.
RunsOn provides three SigNoz dashboards for Flex and Fleet, one per question:
| Dashboard | Answers |
|---|---|
| RunsOn · Operations | Are jobs succeeding and starting quickly, how much capacity and money do they use, and what failed? Start here. |
| RunsOn · Runners | How much CPU and memory does each job use, per runner and across runs? Use it to right-size runners. |
| RunsOn · Troubleshooting | Why are jobs slow to start or capacity stuck? Backlog, launch attempts, Fleet claims, pools, AWS and GitHub latency, and rate limiting. |
Prerequisites#
- RunsOn v3.2 or later.
- OTLP metrics and logs sent to the same SigNoz workspace.
- Delta metric temporality. See Configure RunsOn.
- OTLP log export enabled. Terraform defaults
otel_logs_enabledtotrue; set it explicitly if your module configuration overrides defaults.
Flex publishes service.name=runs-on-flex; Fleet publishes service.name=runs-on-fleet. Both need a deployment.environment resource attribute so the dashboard can filter an environment reliably. It defaults to the stack environment. If that name clashes with your applications’ environments, set another one with otel_resource_attributes, for example deployment.environment=ci.
Operations and Troubleshooting need only control-plane telemetry. Runners needs runner host metrics, which runners export when their runner spec includes extras=otel; see OpenTelemetry.
Configure RunsOn#
For a Terraform Flex or Fleet module, configure the OTLP endpoint and authentication headers for your SigNoz ingestion endpoint:
otel_exporter_endpoint = "https://your-signoz-ingest-endpoint"otel_exporter_headers = "signoz-ingestion-key=<your-key>"otel_exporter_temporality = "delta"otel_logs_enabled = trueotel_traces_enabled = trueUse the endpoint and header format supplied by your SigNoz deployment. The header is sensitive input; keep it in your usual secret-management path rather than committing it to Terraform.
For a Flex CloudFormation stack, configure OtelExporterEndpoint, OtelExporterHeaders, and set OtelExporterTemporality to delta. See OpenTelemetry for the full configuration and signal contract.
Use delta temporality. SigNoz computes a cumulative counter’s increase from the difference between consecutive samples, so it never counts the first sample of a new series. RunsOn job counters are split by repository, workflow, conclusion, instance type, lifecycle, and pool, and each new control-plane task or version starts new series. With cumulative export, the counter panels undercount: Launch attempts in Troubleshooting can show 0 for a burst of jobs that each land in a new series. Delta export reports every increment, including the first.
If your stack already exports cumulative metrics, switch it to delta. The counter panels are accurate from the switch onward; earlier data keeps its gaps. The dashboards read both kinds of data, so they need no change.
Import the dashboards#
- Download the dashboards you want:
runs-on-operator-dashboard.json↗ (Operations)runs-on-runners-dashboard.json↗ (Runners)runs-on-troubleshooting-dashboard.json↗ (Troubleshooting)
- In SigNoz, open Dashboards.
- Create a dashboard and choose Import JSON.
- Import a file, then select an Environment. Repeat for each dashboard.
- Narrow by the other filters as needed. Each dashboard shows only the filters its panels honor.
The dashboards cover both products. Flex pool panels are empty for Product=fleet; Fleet desired-runner and claim panels are empty for Product=flex.
Operations#
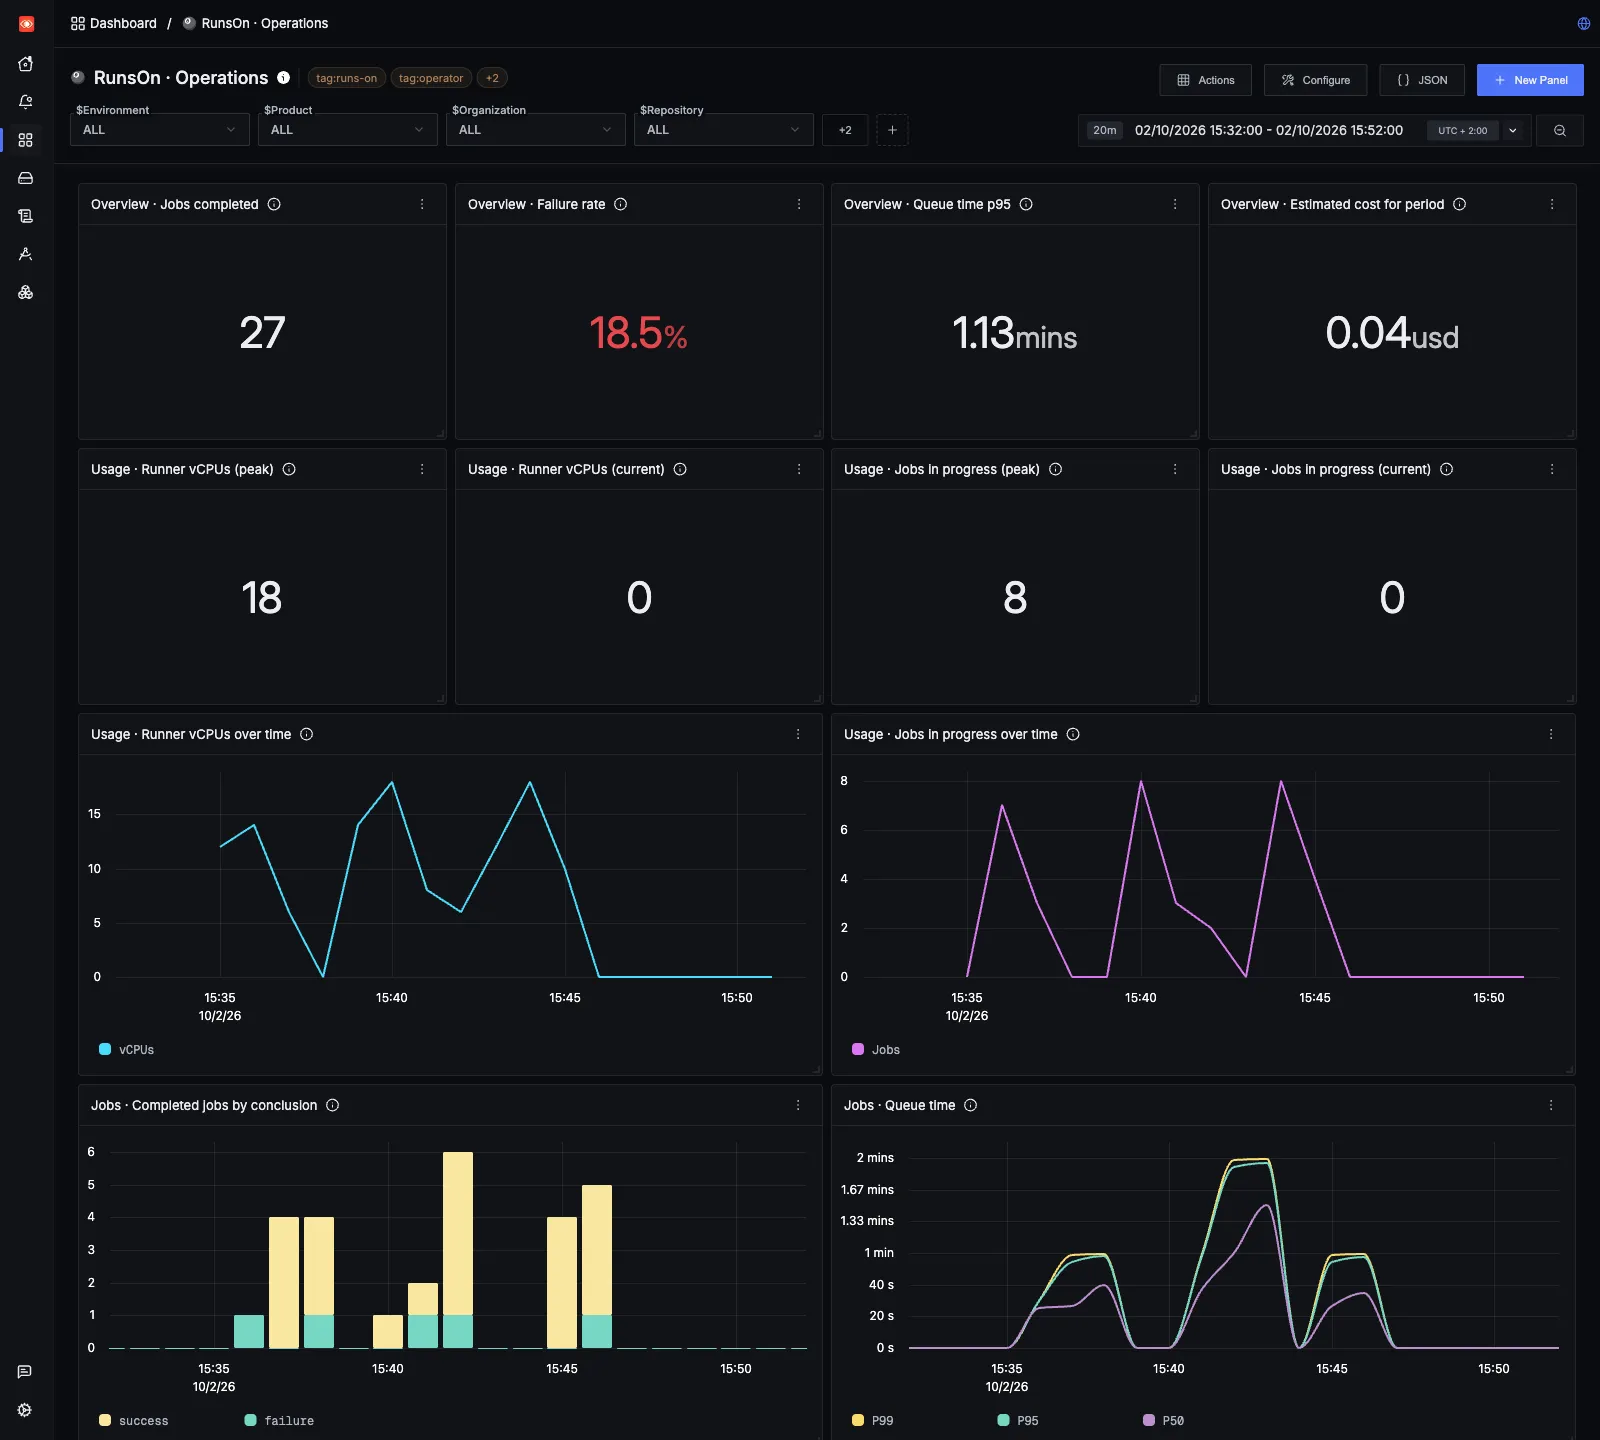
- Overview cards show completed jobs, the failure rate (cancelled and skipped jobs excluded), p95 queue time, and the estimated cost of the period.
- Usage shows runner vCPUs and jobs in progress; see Usage over time.
- Jobs charts completed jobs by conclusion, and queue time from GitHub queueing to job start.
- Cost charts estimated spend by product and the retained sticky snapshot estimate.
- Reliability charts provisioning failures and Spot interruptions. Both stay empty while nothing fails.
- Drill-down tables rank workflows, then jobs, by estimated cost, with runner time, run count, and average duration and queue time. Click a cell and choose Dashboard Variables → Set to filter the dashboard to it.
- Incidents shows warning and error frequency and recent error and Spot interruption events.
Time-series panels use native OTLP metrics. Structured logs provide outcome, cost, and incident detail:
job_launchedfor launch volume and runner context;job_summaryfor outcomes, duration, and estimated cost;operator_snapshotfor current state and pricing-cache health;spot_interruptionand normal error logs for incident investigation.
The workflow and job drill-down tables use job_summary. They retain unpriced jobs for run and duration statistics, while cost-only views only use available estimates.
Usage over time#
The Usage panels show how much runner capacity you use and how many jobs run at once:
- Runner vCPUs totals the vCPUs of active runner instances, from
runs_on_runner_vcpus. Flex counts the instances attached to a job. Fleet counts each instance from launch until its job’s completion is settled, including idle registered runners waiting for a job. Warm-pool standby instances are not included. - Jobs in progress counts the jobs running on RunsOn runners, from
runs_on_jobs_in_progress. Booting, idle, and warm runners are not jobs.
Each view has a card with the peak for the selected time range, a card with the current value, and a time series. Each point of the time series is the total at the end of its interval, so it never adds up values from different moments; the peak card is the highest of those points, so a burst between two of them is not seen. A control plane reports zero usage as it shuts down, so a restart is not counted twice. RunsOn samples both values each time it exports metrics, every 10 seconds by default. The views follow the Environment, Product, and Lifecycle filters. They need RunsOn v3.5.0 or later.
Without SigNoz, chart the same values from CloudWatch Logs Insights, or from any OTLP backend with sum(runs_on_runner_vcpus) and sum(runs_on_jobs_in_progress).
Runners#
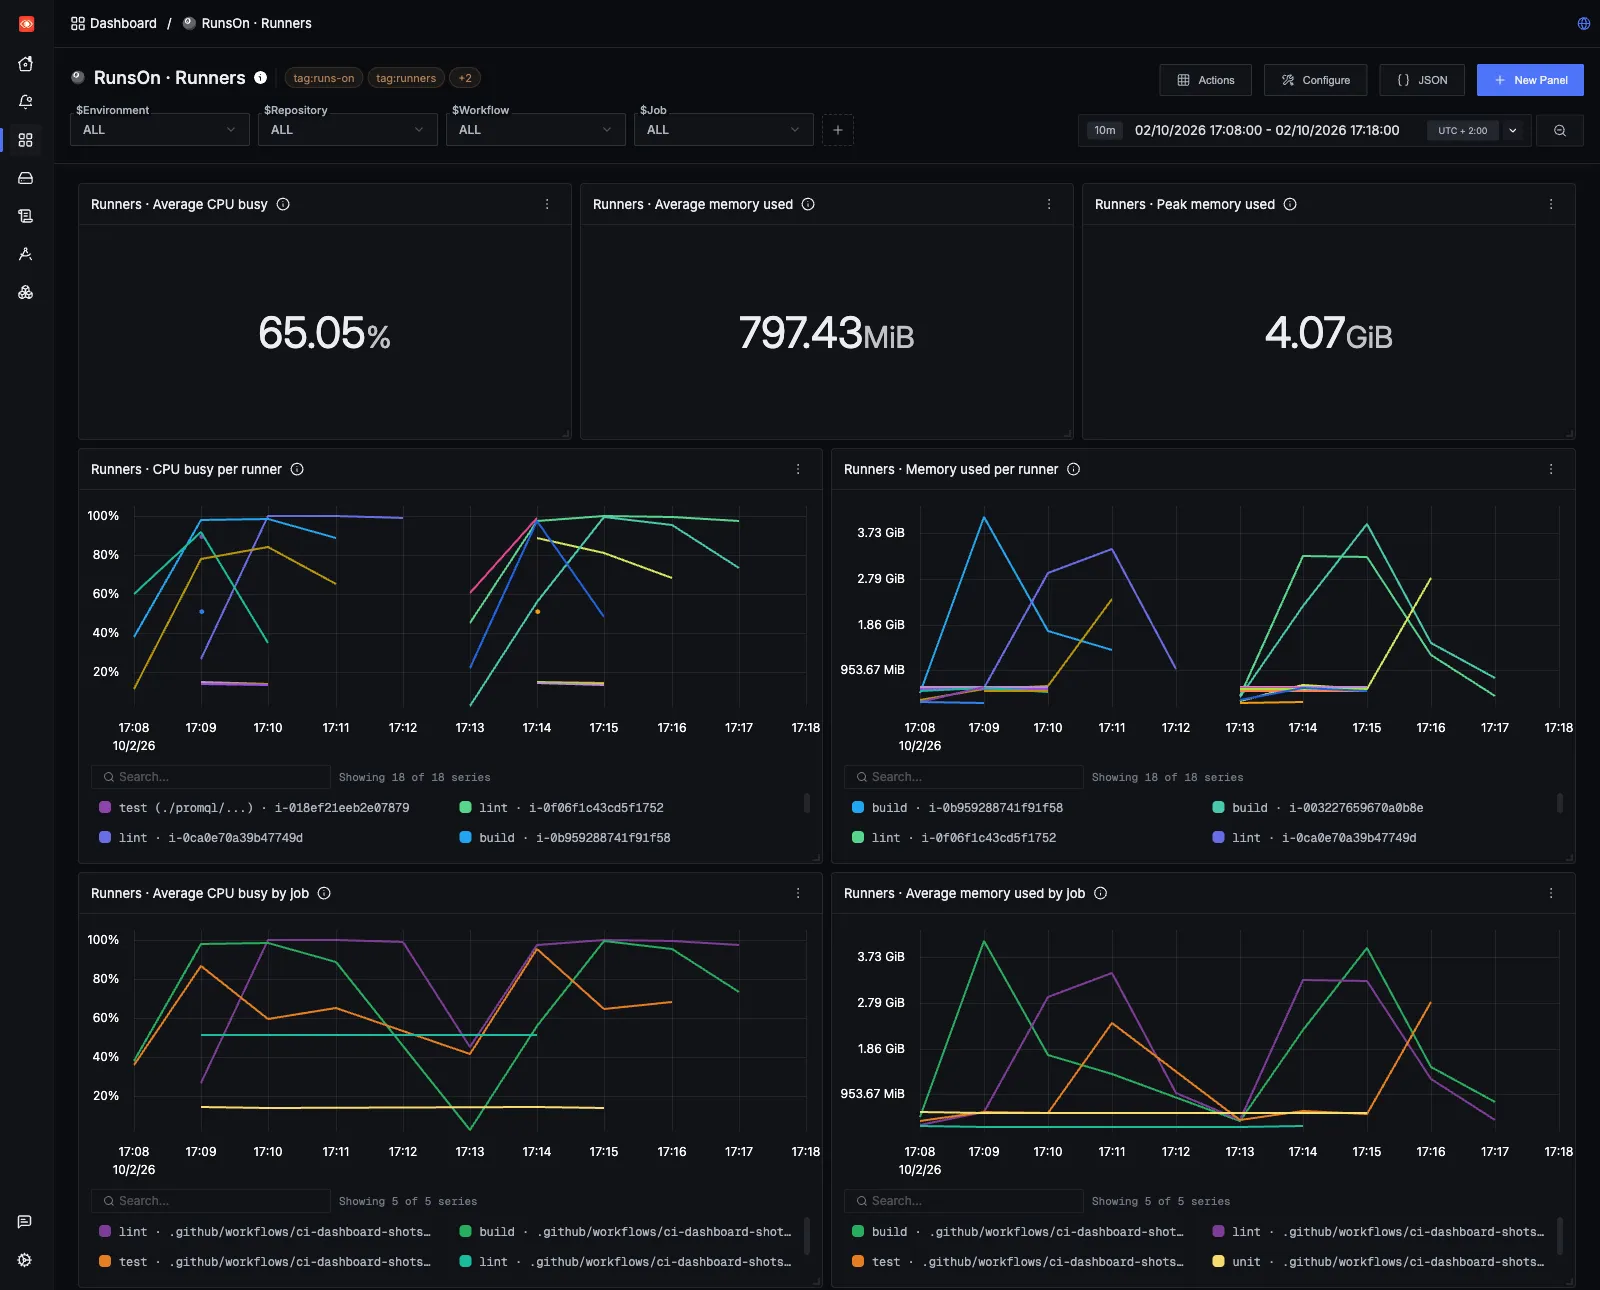
The Runners dashboard reads the host metrics each runner exports while it serves a job:
- CPU busy is the share of CPU time that is not idle (
system.cpu.utilization), averaged across the runner’s cores. The CPU card and the per-job CPU graph pool the cores of all the runners they cover, so a runner with more cores weighs more; the table below weighs runners equally. - Memory used is
system.memory.usagewithstate=used, in bytes. The memory graphs plot the highest value in each interval, so short peaks such as a link step stay visible. Memory in bytes and the job key need RunsOn v3.5.0 or later.
Runners attach the repository, workflow path, and job name once they know their job, and the job key when it starts. The graphs and cards only read samples that carry the job key, so time spent booting or idle is excluded, and runners from older releases appear only in the table. GitHub appends matrix values to job names, for example test (ubuntu, 20). The job key is the job’s key in its workflow file (GITHUB_JOB, here test), shared by every matrix combination. The Job filter and the per-job panels use it, so a matrix job’s runners are compared together, while the per-runner legends keep the full job name. The per-job panels also separate jobs by workflow, repository, and environment, since two workflows can each have a build job.
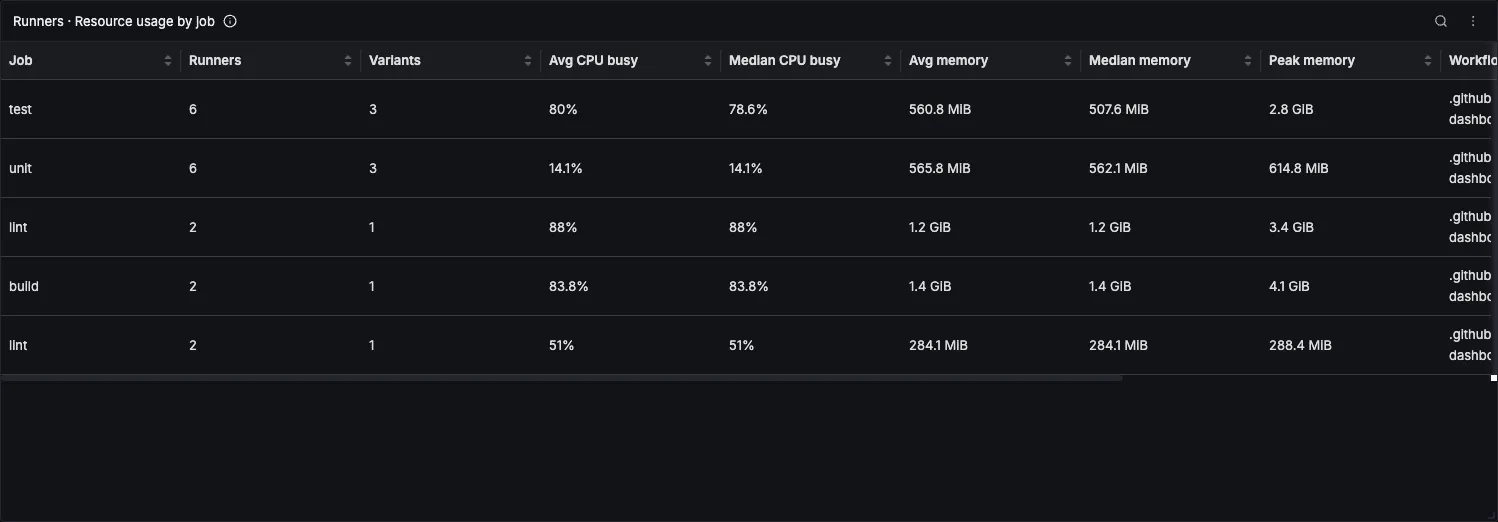
Resource usage by job summarizes each job over the selected time range: how many runners ran it and how many matrix variants they covered, the average and median across runners of their average CPU busy and memory used, and the highest memory any of its runners used. The median keeps one unusual run, such as a build that failed early, from skewing the picture. The table uses a ClickHouse query, so it ignores the dashboard filters and lists every environment.
A job with a low median CPU busy and a peak memory well below the instance’s memory is a candidate for a smaller runner; one whose peak memory approaches the instance’s memory risks running out of it.
Troubleshooting#
The Troubleshooting dashboard groups the signals that explain slow launches and stuck capacity: the Spot circuit breaker, cost-estimate coverage, control-plane backlog, jobs awaiting launch by reason, runner instances by lifecycle and state, launch attempts, Flex pool inventory, Fleet desired runners and claims, provisioning latency and retries, AWS and GitHub API latency and outcomes, and rate limiting.
Read cost estimates correctly#
Job cost is an immediate operational estimate, not an AWS invoice. It includes EC2 compute and live root/sticky EBS usage. Retained sticky snapshots appear separately as an hourly upper-bound estimate based on full volume size; AWS bills only changed EBS blocks.
When pricing or durable launch inputs are missing, RunsOn omits cost rather than recording zero. A drill-down group with no priced summaries can therefore display $0 while still containing jobs. Use Cost estimate coverage in Troubleshooting before using a cost chart to make a billing decision.
The imported dashboards include visual thresholds but do not create SigNoz alert rules. Create alert rules in SigNoz for the signals and thresholds that match your operating policy.